
How Valkey 9.0 reduces the large object noisy neighbor problem
Imagine you have a Valkey cluster handling 100K requests per second, each serving 1 KB objects. Latency is tight. Then a new workload begins fetching a few 10 MB blobs at ten requests per second. Suddenly, the small-object workload experiences a sharp increase in tail latency.
10MB items are common in media use cases, like a live origin caching video segments, which is one of the workloads we run at Momento. We're sensitive to tail latencies in this kind of workload since a p99 spike means buffering for end users. This is particularly problematic in multi-tenant systems where one workflow's large items can affect the experience for everyone else.
The Problem
Our baseline: 100K req/s total of 1KB GETs distributed across 256 connections, each pipelining 32 requests. Then we introduced 10 req/s of 10MB GETs as background traffic. Just 10 requests per second of large objects.
Here's what happened to the 1KB request latency on Valkey 8.1:
| 1KB Latency | p50 | p90 | p99 | p99.9 | p99.99 | max |
|---|---|---|---|---|---|---|
| 8.1 baseline | 295µs | 352µs | 416µs | 489µs | 578µs | 2.80ms |
| 8.1 + 10MB noise | 289µs | 350µs | 500µs | 26.2ms | 30.1ms | 37.2ms |
p50, p90, and p99 barely moved. But tail latencies exploded. p99.9 went from 489µs to 26.2ms. That's 53x worse. A handful of large object fetches were destroying the experience for everyone else.
But wait. Valkey has I/O threads. We saw throughput scale nearly linearly with I/O thread count. Shouldn't they handle the network traffic without blocking the main thread?
The Hypothesis
We knew Valkey 9.0 shipped with reply copy avoidance. The idea: instead of copying large objects into reply buffers on the main thread with memcpy, just pass a pointer reference and let the I/O threads handle the actual data transfer.
If the main thread was blocking on 10MB memcpy operations, that would explain why small requests were getting stuck. Remove the copy, remove the block, problem solved. That was the theory.
How Copy Avoidance Works
Prior to 9.0, returning a large string meant the main thread copied the entire object into a reply buffer with memcpy before moving on. A second copy would then copy the reply out to the network. Two copies per GET.
BEFORE (Valkey 8.1)
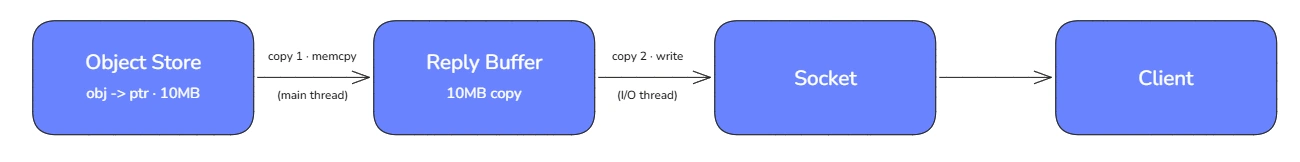
Main-thread memory bandwidth: 10MB per GET.
Valkey 9.0 flips the script. Instead of copying 10MB, the main thread writes a 16-byte reference and moves on:
AFTER (Valkey 9.0)
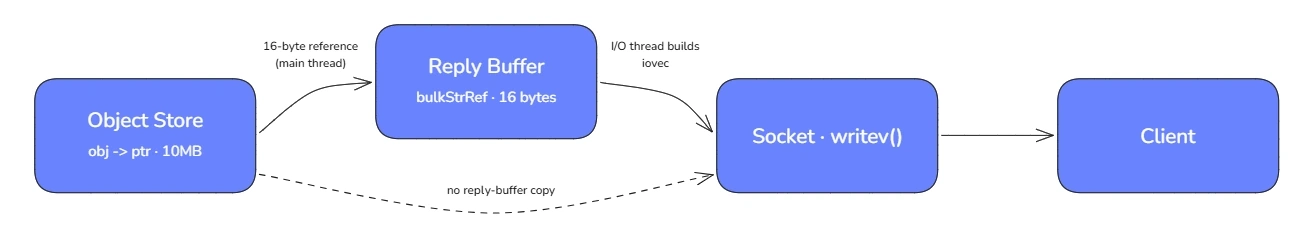
Main-thread memory bandwidth: ~0 — just pointer/reference management.
The reply path builds an iovec, a pointer-and-length pair describing one region of memory, aimed straight at the stored object itself. It hands an array of them to writev(), so the payload never gets copied into Valkey's reply buffer at all. The kernel still copies it to the socket, and writevToClient() loops over partial writes, yielding after 64KB per event so a single large reply can't monopolize the loop. With I/O threads enabled, that work also moves off the main thread and overlaps command execution.
The Verdict
Would copy avoidance fix the noisy neighbor problem? We ran the mixed workload test on both versions:
| 1KB Latency | p50 | p90 | p99 | p99.9 | p99.99 | max |
|---|---|---|---|---|---|---|
| 8.1 baseline | 295µs | 352µs | 416µs | 489µs | 578µs | 2.80ms |
| 8.1 + 10MB noise | 289µs | 350µs | 500µs | 26.2ms | 30.1ms | 37.2ms |
| 9.0 baseline | 291µs | 346µs | 403µs | 479µs | 557µs | 3.26ms |
| 9.0 + 10MB noise | 295µs | 360µs | 799µs | 3.10ms | 5.80ms | 11.9ms |
In 9.0, the long tail holds up. p99.9 under noise drops from 26.2ms to 3.10ms, and max from 37.2ms to 11.9ms. The main thread isn't blocking on memcpy, so small requests keep flowing even when large ones are in flight.
The noisy neighbors are still there. They just stopped keeping everyone else awake.
What To Do Next
If you are serving large objects out of Valkey today, the path is short.
Move to at least Valkey 9.0, enable I/O threads, and re-run your own mixed workload watching p99.9 rather than p99.
If your results look different from ours, the community wants to hear about it. Bring them to Slack or the community page.
Special thanks to Madelyn Olson for guidance on how parameters work and for technical feedback on benchmark methodology.
 Slack
 GitHub
 LinkedIn
 X.com
 YouTube
 Connect
